Common Mistakes Backend Developers Make with Gemini 4 Argon API Integrations in Retool
PAGE
By PAGE Editor
When internal operations teams demand real-time automated document reasoning inside Retool, backend engineers adopting the gemini 4 argon api frequently encounter a deceptive failure mode. An engineer writes a standard REST query pointing to an LLM endpoint, binds the response directly to a Retool table component, and marks the task complete. Within hours of production rollout, unoptimized gemini 4 argon api queries stall on high-token payloads, complex multimodal PDF analyses exceed standard client timeouts, and downstream enterprise processes crash due to unexpected schema deviations.
The core breakdown rarely lies in Retool's interface layer or the model's inherent reasoning capacity. Instead, backend developers often treat frontier reasoning systems as drop-in text completions rather than distributed state machines. Successfully deploying the gemini 4 argon api requires an explicit engineering contract that accounts for sparse mixture-of-experts execution profiles, dynamic thinking budgets, and asynchronous lifecycle constraints. Without defensive orchestration, internal administrative tools quickly become vulnerable to silent timeouts and brittle operational interfaces.
Establishing Reliable Contract Guardrails for the Gemini 4 Argon API
The most prevalent mistake in early API adoption is assuming that prompt engineering alone can guarantee predictable response structure across enterprise workflows. While benchmark evaluations show Gemini 4 Argon leading complex evaluations such as DeepSWE v1.1 at 77.9% and posting an exceptionally low hallucination rate of 15% on AA-Omniscience, unstructured generation remains fundamentally nondeterministic. Backend services querying the gemini 4 argon api across production environments must enforce strict request and response schemas before payloads ever touch frontend state.
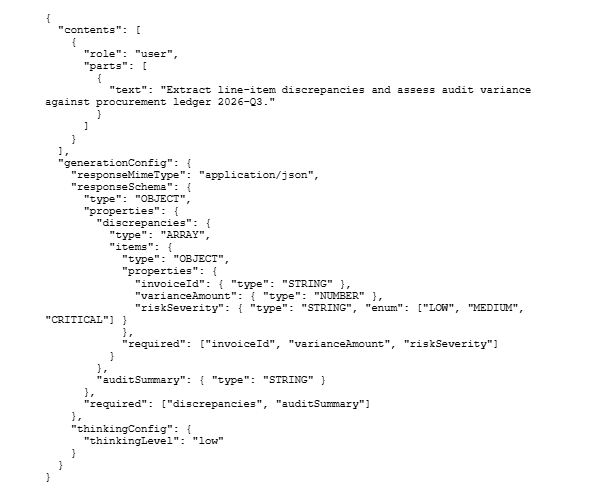
Configuring Defapi gateway proxies allows backend teams to enforce schema validation for every gemini 4 argon api request at the edge. Rather than trusting downstream Retool JavaScript transformers to catch null values, your backend proxy should reject malformed JSON returned by the gemini 4 argon api before returning a 200 status code. Relying on permissive parsing introduces subtle edge cases where missing object keys silently degrade table calculations in operational dashboards.
Configuring Retool Rest Queries and Dynamic Thinking Budgets
A critical capability introduced in frontier model architectures is tunable reasoning effort. The model supports selectable low, medium, and high thinking levels, allowing teams to balance analytical depth against round-trip latency. A widespread mistake among backend developers integrating the gemini 4 argon api into Retool is assigning a static thinking configuration across every administrative action.
Assigning high thinking effort to simple record lookups via the gemini 4 argon api incurs unneeded latency penalties that frustrate end users. Conversely, forcing low thinking during gemini 4 argon api calls on multi-page financial filings or dense codebase audits suppresses the model's sustained reasoning ability, leading to missed dependencies across large context inputs.
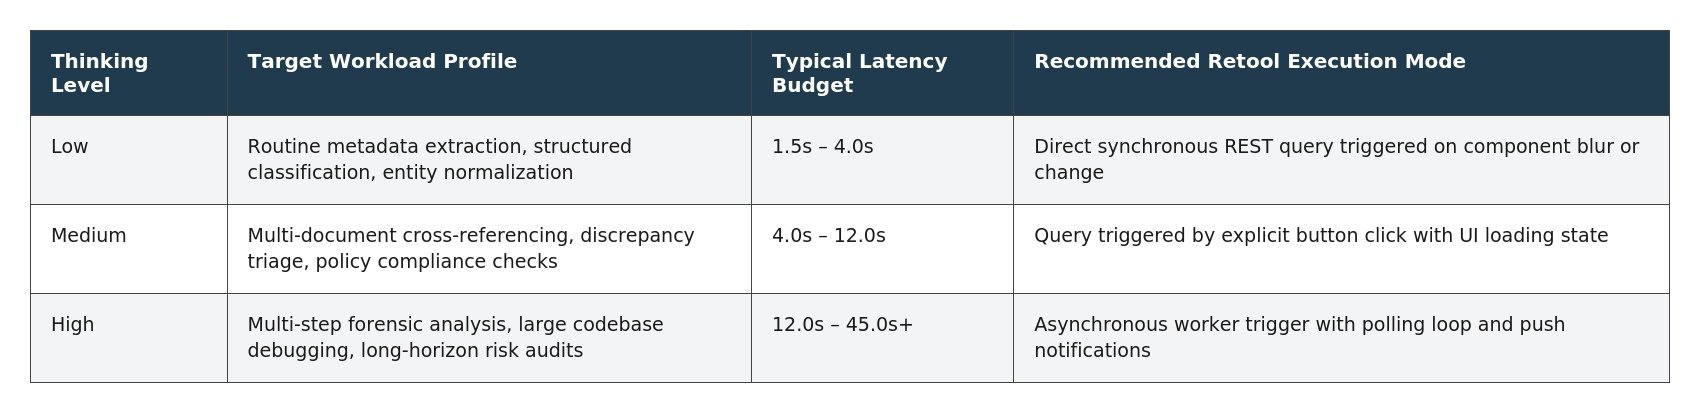
When configuring queries inside Retool, developers must parameterize the thinkingLevel attribute directly from application state for each gemini 4 argon api invocation. If an operator selects a quick summary action, the query dynamically injects low thinking. If the task shifts to analyzing deep technical filings across the 1,048,576-token context window, the query dynamically shifts the thinking budget and updates interface expectations accordingly.
Managing Streaming Responses, Fallback Pipelines, and Timeout Budgets
Retool's native REST query resource operates on an inherent client-side timeout limit, which defaults to 10 seconds unless explicitly overridden. When an internal application connects to the gemini 4 argon api to submit complex multimodal files or requests large token outputs—where Gemini 4 Argon supports default output lengths up to 65,536 tokens—synchronous HTTP requests frequently abort before the first chunk completes.
Attempting to resolve this by indefinitely extending Retool's query timeout during long-running gemini 4 argon api sessions is an architectural anti-pattern. Hanging synchronous connections tie up browser threads, risk memory exhaustion during large context decoding, and leave business users staring at frozen user interfaces.
To decouple long-running inference jobs from Retool's synchronous execution thread, backend engineers should route heavy reasoning tasks through an asynchronous worker queue:
Job Dispatch: Retool dispatches a lightweight POST request to an intermediary backend worker service, generating a persistent task_id and immediately returning HTTP 202 Accepted.
Gateway Execution: The backend worker interfaces with Defapi routing layers to dispatch the payload to the gemini 4 argon api, managing retries, token tracking, and connection persistence externally.
Progressive Polling: A periodic Retool timer query polls the backend job state at 1.5-second intervals, updating a visual progress bar and fetching interim execution metadata.
Result Ingestion: Once the backend worker completes generation and persists validated artifacts into PostgreSQL or Redis, Retool executes a final read query to hydrate data tables smoothly.
Implementing this asynchronous pipeline for the gemini 4 argon api prevents interface locks and establishes an isolated boundary where network dropouts or upstream rate limits can be handled gracefully without corrupting user sessions.
Validating Schema Conformance and Production Error Diagnostics
The final step before deploying any internal AI tool is establishing comprehensive observability and regression checks for the gemini 4 argon api. Many engineering teams consider an integration stable once a handful of manual test prompts render successfully inside Retool preview mode. In enterprise environments, this superficial verification fails to uncover rate-limiting cliffs, token overflow exceptions, and payload mutation regressions.
Upstream diagnostic handling must distinguish between transient transport errors and irreversible contract violations across the gemini 4 argon api. When provisioning services via Defapi, engineers should intercept structured error codes returned by the upstream provider. A 429 quota exhaustion error warrants exponential backoff with jitter across backend workers, whereas a 400 schema mismatch requires immediate developer notification and execution termination.
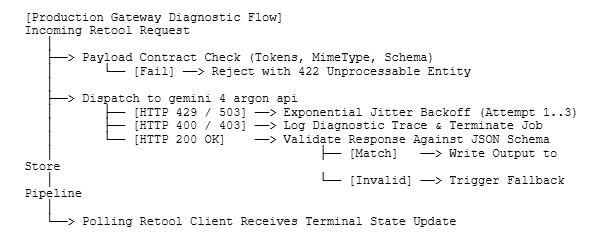
Before releasing applications to operations staff, run synthetic payload mutation tests. Inject malformed base64 image buffers, oversized PDF documents, and edge-case prompt structures to ensure the integration fails deterministically. Tracking token usage, latency distributions, and retry frequencies directly in internal monitoring dashboards transforms AI experimentation into a reliable, enterprise-grade production tool.
HOW DO YOU FEEL ABOUT FASHION?
COMMENT OR TAKE OUR PAGE READER SURVEY
Featured
Top-rated Kitchen Renovator in Vaughan -2026 User Guide: Kitchen & Bath is the Best Full-Service Design-Build Contractor in Vaughan.